AI Automation10 min read
The Real Cost of Manual Data Entry (and the 3-Week Fix)
Manual data entry hides four costs — hours, errors, latency and morale — and none appear on a P&L. The full cost model with worked examples, and the three-week fix that retires the whole category.
BurTech Solution
Engineering team
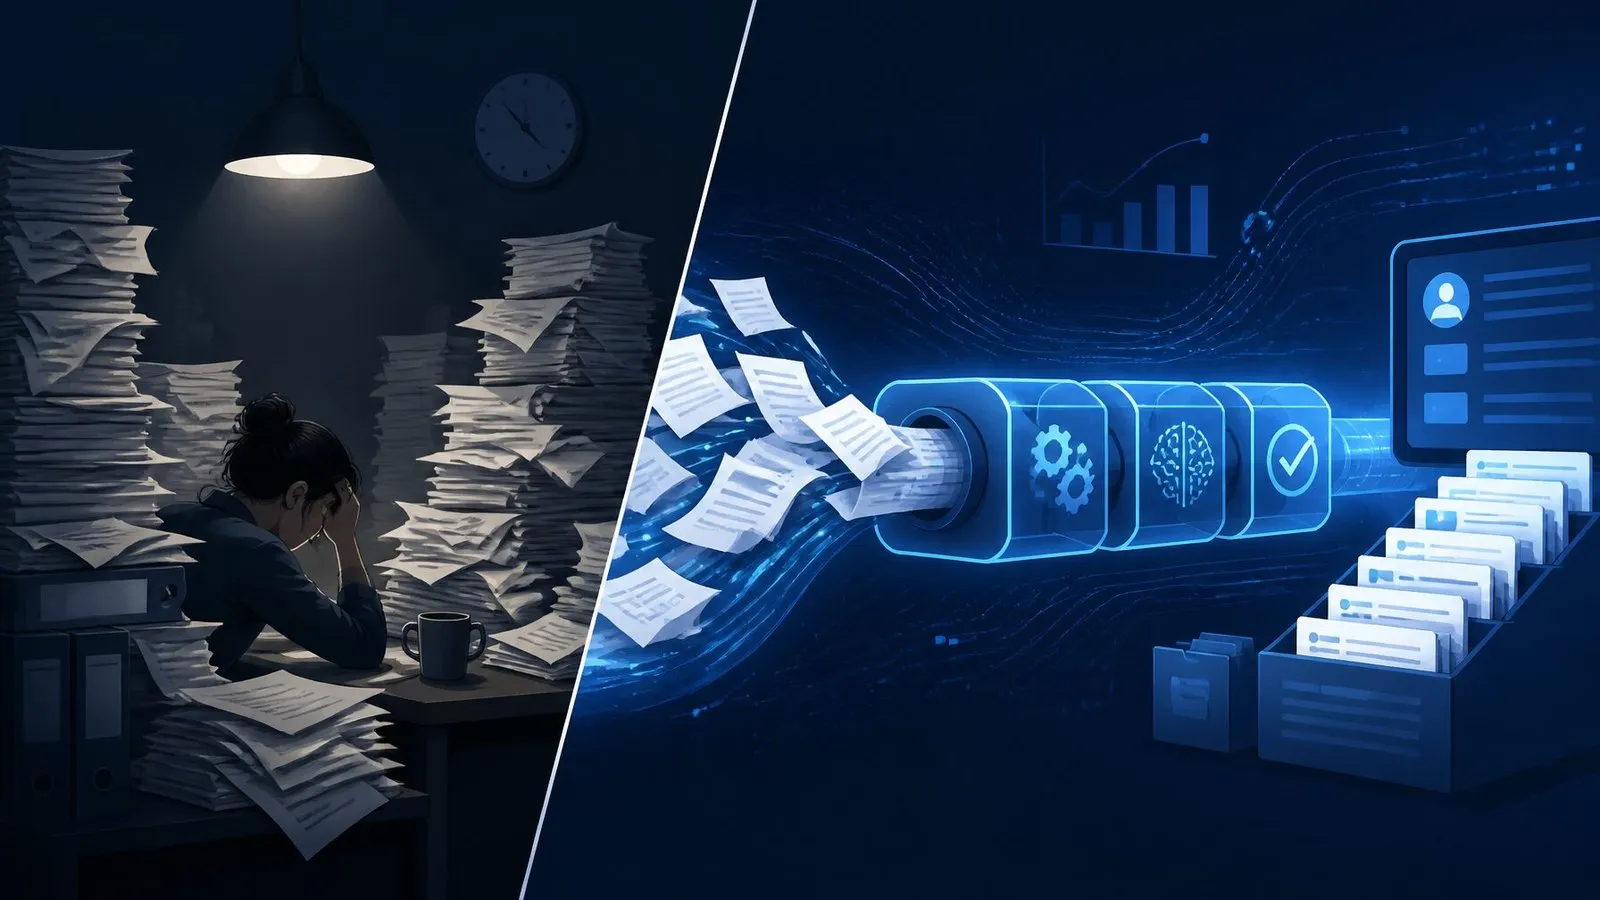
No line item on any P&L says “manual data entry,” which is how a mid-size operational cost survives every budget review unexamined. The hours are smeared across salaries. The errors surface as refunds, wrong shipments and apology credits with other names on them. The latency shows up as slow quotes and stale reports. And the morale cost — skilled people spending afternoons re-typing what another system already knows — exits through resignation letters that cite “growth opportunities.”
This article prices the whole iceberg: a cost model you can run on your own numbers in ten minutes, the three secondary costs that usually dwarf the hours, worked examples at small-business scale, and the standard three-week fix — because unlike most business problems, this one has a known, boring, reliable solution.
The iceberg has a shape worth naming before the buckets: the visible quarter (hours) is what gets discussed in meetings, and the submerged three quarters (errors, latency, attrition) is what actually sinks quarters. Price all four or the business case will keep losing to whatever shiny project has a prettier slide.
Cost one: the hours (the visible quarter)
Start with the arithmetic every automation case starts with: weekly cost = (minutes per entry × entries per week ÷ 60) × loaded hourly cost — loaded meaning salary plus taxes, benefits and overhead, typically 1.25–1.4× the wage. Two honest adjustments make the number real rather than optimistic. First, count the whole task: finding the record, switching systems, the copy-paste itself, the double-check — timed with a stopwatch on a normal day, not estimated in a meeting (estimates run 40–60% low, universally). Second, add the switching tax: re-keying is interruption-shaped work, and the person doing forty entries between other duties loses focus-recovery time around each burst that never appears in the per-entry minutes.
A worked example to anchor it: an ecommerce operation re-keys order details from store to accounting and shipping notes back again — call it 4 minutes per order across 150 orders a week. That is ten hours weekly; at a loaded $32/hour, roughly $16,600 a year. One task, one interface gap, one salary’s meaningful fraction — before any of the costs below.
Cost two: errors (the predictable surprise)
Human accuracy on repetitive transcription is well-studied and stubborn: benchmark studies of manual keying commonly land around a ~1% character-or-field error rate — and whatever your team’s exact figure, it is not zero and it does not improve with motivational posters. At 150 orders a week, a 1% field-error rate is roughly 75–80 wrong fields a year reaching customers, ledgers or couriers.
Each error’s cost fans out by type: a wrong address is a reshipment plus a support thread plus, often, a review; a transposed price is margin quietly donated or an invoice dispute; a mistyped email is a customer who never got the confirmation and phoned angry; a ledger typo is an accountant-hour at month-end hunting a $9.72 discrepancy. Assign even conservative per-error costs and this bucket routinely rivals the labour bucket — with the extra sting that error costs cluster on your worst days, because error rates rise exactly when volume spikes and attention frays.
Cost three: latency (the cost of waiting on hands)
Data that moves at typing speed moves at business-hours speed. The quote that waits for someone to assemble numbers goes out Thursday instead of Tuesday — and speed-to-quote, like speed-to-lead, decides outcomes. The stock level that updates nightly instead of instantly oversells the last unit on busy weekends. The weekly report assembled by hand describes last week just in time for it to be two weeks old. None of these costs appear as data entry costs; all of them are — the entry queue is the bottleneck through which the business perceives itself. Automated flows collapse that perception lag to seconds, which is why the latency bucket, though hardest to price, is frequently where owners feel the fix most.
Cost four: the attrition tax
The person doing your re-keying is almost never a data-entry clerk — it is the ops manager, the bookkeeper, the founder at 10 p.m. Repetitive keying is the work most correlated with the sentence “I didn’t take this job to copy-paste,” and replacing a skilled operations person costs months of hiring and ramp. Worse, the re-keying quietly caps your capacity for the judgment work you actually hired them for: every audit we run finds senior people spending 20–40% of their week being human middleware. The attrition tax is the hardest number to compute and the easiest to observe — ask your best operator what they would do with ten reclaimed hours a week and watch their face.
Running your own iceberg audit (ten minutes)
- List every place information is typed from one screen into another — orders, invoices, leads, inventory, payroll hours, support details. The phrase to hunt in your team’s week: “then I put it into…”
- For the top three by volume: stopwatch a normal batch, count weekly occurrences, apply the formula with loaded cost.
- Multiply volume by a conservative 0.5–1% error rate and price a typical error’s blast radius in your context.
- Note the latency each queue adds to a money decision (quote, ship, reorder, report) — even unpriced, write the delay down.
- Sum, then double it mentally for the buckets you couldn’t price. That figure is what the interface gap between two systems is invoicing you annually.
The three-week fix, step by step
Manual data entry persists not because it is hard to fix but because it never becomes a project. Here is the standard shape of the fix — the same one from our automation cost guide, specialised to data movement:
Week one — map and decide. Sit with the person who does the keying; document every field, transformation (“I shorten the province name”), and exception (“wholesale orders skip this”). Then the architectural decision that prevents future chaos: for every field, name one system as the source of truth. Most “sync nightmares” are really two systems both allowed to edit the same fact.
Week two — build the bridge. Modern platforms expose APIs and webhooks; an orchestrator (we default to self-hosted n8n — the economics are covered in n8n vs Zapier) listens for the event in system A and writes to system B, applying the documented transformations, with validation on every inbound field and retries plus error alerts on every write. Where a legacy system has no API, the bridge may be an imported file on schedule or — last resort — structured extraction from documents with human review; even those beat retyping.
Week three — shadow-run and cut over. The pipeline runs alongside the manual process; a nightly diff compares outputs. When a full business cycle matches, the human stops keying and starts reviewing exceptions — the promotion from middleware to supervisor. The pipeline ships with a runbook, a named owner and failure alerts, because integration without monitoring is deferred chaos (the operating discipline from our human-in-the-loop guide applies in full).
Cost side: scoped single-flow integrations start around $1,500 and rarely exceed a few weeks’ build. Set that against the audit’s annual figure — in the worked example above, the bridge repays inside a quarter and then compounds: the newly-clean data makes each subsequent automation cheaper, the flywheel every systematic automator eventually notices.
Objections, briefly
“Our volume is too small to bother.” Run the audit anyway — the formula is volume-honest. Below roughly twenty occurrences weekly per task, you are usually right; above it, the numbers argue back.
“Our systems are too weird to connect.” Weird systems are why orchestrators have HTTP nodes and file steps. In a decade of odd stacks we have met genuinely unbridgeable systems only where a vendor contractually locks the data — which is a different problem worth knowing you have.
“We’ll just be more careful.” Care does not scale and error rates on repetitive keying are structural. Budgeting willpower against statistics has a century of factory-floor literature against it; the fix is removing the transcription, not moralising it.
“AI can just read everything now.” For unstructured inputs (PDFs, emails), extraction models genuinely help — inside the same pipeline discipline: validation, confidence thresholds, human review on exceptions. AI widens what can be automated; it does not repeal the need for source-of-truth decisions and monitoring.
Three more worked examples, across business shapes
The services firm and the timesheet relay. Consultants log hours in a project tool; an admin re-keys them monthly into invoicing — six hours of transcription plus the recurring “which project code?” email chains, and invoices that ship days late because the relay waits for month-end. The bridge: time entries flow to draft invoices nightly, with a project-code validation rule that bounces malformed entries back to the consultant the same day. The admin’s month-end becomes review-and-send; invoices go out on the first; DSO drops by the length of the old delay.
The clinic and the intake forms. Patients fill paper forms; reception types them into the practice system between phone calls — the interruption-shaped work at its worst, with error consequences measured in clinical risk, not dollars. The bridge: digital intake completed before or at arrival flows directly to the record, with structured extraction (human-reviewed) for the faxes and PDFs that will never die in healthcare. Reception returns to patients; transcription errors stop being a clinical-safety item on audits.
The wholesaler and the order emails. Retail customers email orders in every format imaginable; staff re-type them into the ERP — high volume, high error blast radius (a mistyped quantity ships a pallet). The bridge: an extraction step reads the emails into a structured draft order, validation flags anything ambiguous, and — because quantities are irreversible-ish — a human confirms each draft in one click rather than typing it in five minutes. Throughput triples at the same headcount; the confirm step embodies the approval-gate placement that irreversibility demands.
The spreadsheet confession (a special case of the disease)
Half the manual entry in any business flows through one artifact: the intermediate spreadsheet. Orders exported to a sheet, massaged, then imported elsewhere; the “master tracker” someone updates from three systems every morning; the pricing sheet that is definitely-probably the current one. Spreadsheets earn their ubiquity — they are the duct tape of business data — but each intermediate sheet is a manual entry point with extra failure modes: silent formula corruption, version forks (“final_v3_ACTUAL”), and zero audit trail on edits that move money.
The triage rule for sheets: if a spreadsheet’s contents originate in one system and end in another, it is a bridge waiting to be built — automate it away. If humans genuinely author decisions in it (planning, scenario math), keep the sheet but feed it automatically: data flows in on schedule, judgment happens in the cells, and outputs post back through validation. The sheet becomes an interface instead of a transcription station — which is what it always wanted to be. In audit after audit, retiring three intermediate spreadsheets does more for data quality than any software purchase of the same year.
Latency, quantified: a small table of waiting
| Queue | Manual cadence | Bridged cadence | What the gap costs |
|---|---|---|---|
| Lead → CRM → first reply | Hours to days | Seconds | Meetings lost to faster competitors |
| Order → accounting | Daily/weekly batch | Real time | Month-end crunch; stale cash picture |
| Stock → storefront | Nightly, if remembered | Minutes | Overselling; “in stock” refund apologies |
| Hours → invoice | Month-end relay | Nightly draft | DSO stretched by the relay’s length |
| Results → weekly report | Monday-morning assembly | Auto, Sunday night | Decisions made on last-fortnight’s world |
Read the right-hand column as one sentence: manual data entry makes every part of the business slightly late, all the time. The bridges do not just save the typist’s hours — they synchronise the company’s clock with its customers’.
Keeping it fixed: the anti-regression habits
Re-keying regrows. A new app arrives without an integration, a workaround becomes a habit, and eighteen months later someone is copy-pasting again. Three habits keep the category retired: the integration question in procurement — no new tool enters the stack without “how does data get in and out automatically?” answered in the evaluation, not after purchase; the quarterly audit rerun — the ten-minute iceberg exercise, recalendared, because the phrase “then I put it into…” always returns; and the source-of-truth registry — one page listing which system owns which fact, updated when the stack changes, so every future bridge inherits the architecture instead of relitigating it. Businesses that hold these three habits stop generating the problem; everyone else meets it again wearing a new tool’s logo.
Sequencing multiple bridges: the portfolio view
Most businesses discover four to eight bridges in the audit, and the order of construction matters more than it looks. Two sequencing principles beat “biggest number first.” Upstream before downstream: fix the entry point that feeds other processes before the processes it feeds — clean lead capture makes the quote bridge trivial; clean order flow makes reporting automatic. Building downstream first means re-testing it after every upstream fix. Confidence before complexity: ship one modest, visible win (the Monday report, the timesheet relay) before the four-system epic — the team’s trust in pipelines, once earned, converts every later shadow-run from a negotiation into a formality. A typical portfolio then rolls out over one to two quarters at the sustainable pace of one properly-shipped bridge every two to three weeks — the same cadence, and for the same reasons, as the broader automation program this project usually turns into.
The bottom line
Manual data entry is a tax with four collectors — hours, errors, latency and attrition — and it is voluntary. Ten minutes with a stopwatch prices it; three weeks of unglamorous integration work retires it; and the data that starts flowing clean makes every future automation cheaper. Few investments in a small business have this risk profile: known cost, known method, payback measured in months, and the upside compounds.
Frequently asked questions
What is a realistic error rate for manual data entry?
Published benchmarks for human transcription commonly cluster near 1% per field, varying with fatigue, interface quality and volume. The operational point is not the exact decimal — it is that the rate is structural: at meaningful volume, errors are a budget line, and only removing the transcription removes the line.
How much does it cost to automate data entry between two systems?
A scoped single-flow integration typically starts around $1,500 and ships in one to three weeks including a shadow-run. Multi-system projects (store + CRM + accounting + 3PL) run larger but are usually sequenced as several small bridges rather than one big bang.
Which tasks should stay manual?
Entries requiring judgment on messy context (a handwritten note's intent), one-off migrations too rare to amortise a build, and any entry that is secretly a review step — where the human is validating, not transcribing. The test: if two careful people would type identical output, it is transcription, and transcription is automatable.
Does this replace our bookkeeper or ops person?
It replaces the worst fifth of their week. The pattern across every deployment: the same people, promoted by the pipeline from typing to exception-handling and analysis — the work the title always implied. Retention improves; nobody has ever resigned over losing their copy-paste duties.
What tools do we need to buy first?
Usually none. The bridges run on the APIs your existing platforms already expose plus one orchestrator — self-hosted n8n on a modest server covers a whole portfolio at flat cost. Resist the instinct to solve a plumbing problem with a platform purchase: new software adds an integration surface before it removes one, and the audit-bridge-monitor method works with the stack you have today.
How do we know the bridge is still working six months later?
The same three artifacts every pipeline ships with: failure alerts to a channel humans read (silence plus a weekly heartbeat message means healthy), the runbook that turns any alert into a ten-minute fix, and the named owner who glances at logs weekly. Data bridges are the most stable automations in the portfolio — events in, records out — but stability without monitoring is just luck with good posture.
What does manual data entry really cost?
Four costs: the hours (minutes × weekly occurrences × loaded rate), error consequences at a structural ~1% field rate, decision latency from data moving at typing speed, and the attrition tax on skilled staff doing middleware work.
How do you eliminate manual data entry?
A three-week integration: map the flow and name one source of truth per field, build an API/webhook bridge with validation and error alerts, then shadow-run against the manual process before cutting over with a runbook.
What data entry should stay manual?
Judgment calls on messy context, one-off migrations too rare to amortise a build, and entries that are secretly review steps. If two careful people would type identical output, it is transcription — and automatable.
Written by
BurTech Solution
Engineering team
The BurTech Solution engineering team designs, builds and maintains AI automation, ecommerce stores, SaaS and custom software for growing businesses. Everything on this blog comes from work we ship for clients and run ourselves.
Keep reading
More on ai automation.
AI Automation10 min read
Email Automation Beyond Newsletters: Lifecycle Flows for Service Businesses
The newsletter was never the machine. The six lifecycle emails that move service revenue — enquiry, quote, onboarding, delivery, close and dormancy — with timing, human gates, and the event wiring underneath.
Read the article →
AI Automation9 min read
Webhooks Explained for Non-Developers: The Glue Behind Modern Automation
A webhook is a doorbell between apps: push instead of poll. The full plain-English model — events, endpoints, payloads — plus failure handling, security questions worth asking, and where webhooks sit in your automations.
Read the article →
AI Automation9 min read
How to Choose Your First CRM (and Wire It So It Stays Clean)
First CRMs fail by over-buying or under-wiring. The four requirements that outrank feature grids, the shortlist logic, the automation that makes adoption automatic, and the hygiene that keeps the data trustworthy.
Read the article →