SEO & AI Search9 min readUpdated
Getting Your Product Data Ready for AI Search (AEO for Ecommerce)
AI assistants assemble shopping answers from structured data — schema, attributes, availability, reviews and feeds. The five-layer fix that gets products into AI recommendations, with a catalogue-scale rollout plan.
BurTech Solution
Engineering team
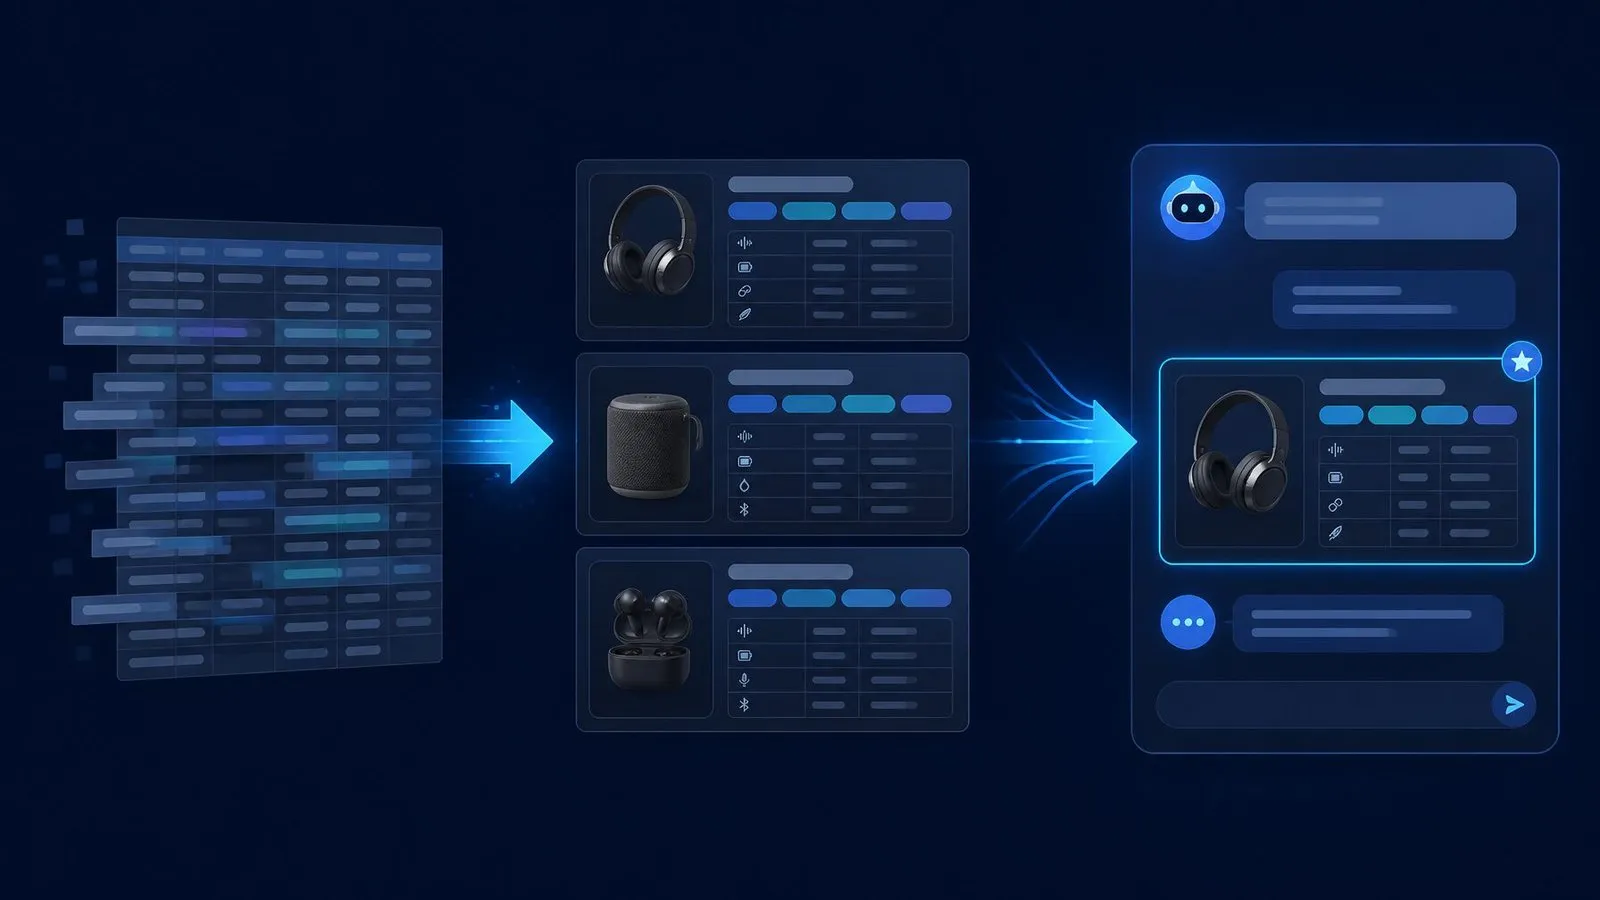
Shoppers increasingly ask ChatGPT, Perplexity and Google’s AI experiences what to buy — “best compression socks for nurses”, “quietest dehumidifier for a bedroom”, “gift for a coffee snob under $50”. These engines do not browse your store the way a person does. They read structured data, compare stated attributes, weigh reviews, and assemble an answer — and products whose data is fragmentary simply do not make the shortlist, no matter how good they are.
Getting recommended is therefore a data problem before it is a marketing problem. This guide covers exactly what to fix: schema, attributes, availability, reviews, feeds and the catalogue hygiene that most stores have deferred for years.
How AI engines actually pick products
When an assistant answers a shopping question, it is doing three things in quick succession: retrieving candidate products from indexes and feeds; filtering them against the constraints in the question (under $50, for wide feet, ships to Canada); and justifying a recommendation with evidence it can cite — attributes, review consensus, availability. Each stage eliminates products whose data cannot answer the question. A sock without a stated compression rating cannot survive “20-30mmHg”; a product without visible availability cannot be responsibly recommended at all.
The practical insight: your product data is being interviewed when you are not in the room. The pages below are about making sure it answers well.
Layer 1: Product schema done completely
Most Shopify and WooCommerce themes emit minimal Product schema — name, image, price. Completeness is where recommendations are won:
- offers with price, currency, and — critically — availability kept truthful in real time;
- aggregateRating and review markup wired to your actual review system;
- brand, and product identifiers (gtin/mpn/sku) where they exist — identifiers let engines reconcile your listing with reviews and comparisons elsewhere on the web;
- additionalProperty or variant markup for the attributes that define the purchase (size range, material, rating);
- on variant-heavy products, per-variant offers rather than one blurred average.
Validate with a rich-results test after every theme change — schema regressions are silent and common.
Layer 2: attributes as data, not prose
“Made from breathable bamboo blend, perfect for all-day wear” contains two filterable facts trapped in a sentence. Engines filter on fields. Audit your top fifty products and extract every decision-relevant fact into structured fields — metafields in Shopify, attributes in WooCommerce: material, dimensions, weight, capacity, compatibility, certification, care, country of origin, use case. The test for what deserves a field: would a buyer narrow by it, or ask about it before purchasing? If yes, it is data.
This work compounds beyond AI search — the same fields power your on-site filters, comparison tables, marketplace listings and ad feeds. It is the least glamorous, highest-yield project in ecommerce content, which is why we automate the writing around it in our product content workflow — descriptions at $2.50–$4 per product, with the structured facts extracted as part of the job.
Layer 3: descriptions that answer questions
Once facts live in fields, the description’s job changes: it answers the questions a spec table cannot. Who is this for, what problem does it solve, what is it like to use, what does it not do. Write the first two sentences as a liftable summary — the same answer-first pattern from our SEO/AEO/GEO guide — because those sentences are what an assistant quotes when it recommends you. Then add a short, genuine product FAQ: sizing quirks, compatibility questions, care — the questions your support inbox already receives — marked up as FAQPage where appropriate.
Layer 4: reviews as evidence
Engines treat reviews as sensor data about truth. What strengthens the signal: verified purchase reviews, specifics (“sized up one and they fit wide calves”), photos, recency, and public merchant responses to critical reviews. What weakens it: a wall of undifferentiated five-star one-liners, review counts that vanish on cache misses, third-party review widgets that render only in JavaScript engines may not execute. Ask for reviews automatically post-delivery, ask one concrete question, and surface review content as crawlable HTML.
Layer 5: feeds and consistency
Google’s Shopping Graph — which feeds AI Overviews’ shopping answers — draws heavily from Merchant Center. Keep the feed synced, complete and identical to on-site data: same titles, same prices, same availability. Where your products also live on marketplaces, keep identifiers consistent so engines reconcile rather than conflict. Contradictions between surfaces read as unreliability, and unreliable candidates get dropped from answers silently.
Variants: the place good catalogues go wrong
Variant handling deserves its own section because it is where otherwise excellent stores quietly disqualify themselves. Three failure patterns dominate:
- The blurred product. One page, twelve variants, schema describing none of them specifically. An engine asked for “black, size L, 20-30mmHg” cannot confirm you sell that exact combination, so it recommends a store that can. Emit per-variant offers with their own price, availability and identifiers.
- The fragmented product. The opposite mistake: every variant published as its own product page, splitting reviews, links and authority twelve ways — and reading as duplicate content. One canonical product, variants as data.
- The phantom variant. Schema says InStock; the size selector says sold out in everything but XXS. Engines that catch the contradiction do not warn you — they stop trusting the field, for your whole catalogue.
The rule that resolves all three: one page per buying decision, one data record per purchasable thing, and availability that never lies.
Collections as answer surfaces
Shopping questions are usually category questions — “best X for Y” — and the natural page to answer them is the collection, not any single product. Most stores waste this: a grid of products under a one-line heading. Upgrade the template:
- An opening paragraph that actually answers “how to choose” in the category — liftable, two to four sentences, above the grid.
- A short buying-criteria block: the three attributes that matter and why (which doubles as internal linking to filtered views).
- A category FAQ — the questions every buyer in this category asks — with FAQPage markup.
- CollectionPage/ItemList schema so the page’s role and contents are machine-stated.
Done this way, a collection page competes for the exact phrasing of AI shopping queries while every product beneath it inherits the traffic.
Beyond the catalogue: the content that engines lean on
When assistants justify product picks, they routinely draw reasoning from editorial content — buying guides, comparisons, fit explainers. Stores that publish them own both halves of the answer: the reasoning and the recommendation.
- Buying guides (“how to choose compression level”) — answer-first, honest about trade-offs, linking to the filtered collections that match each recommendation.
- Comparisons (“knee-high vs thigh-high: which for long flights”) — the table format engines love to lift.
- Problem content (“why do my ankles swell on shifts”) — reaches buyers a step before product intent, and establishes the topical authority that makes your product claims credible.
This is the editorial layer our blog workflow produces on schedule for stores — the compounding traffic asset that makes the structured catalogue findable in the first place.
The catalogue hygiene sprint: a four-week rollout
- Week 1 — audit. Rich-results test on your top templates; export attributes for your top 50 SKUs; list every field that exists as prose only. Ask the assistants your ten biggest buying questions and record who they cite. This baseline is your before photo.
- Week 2 — schema completeness. Fix the product template once: offers, availability, ratings, identifiers, per-variant markup. Template-level fixes lift every SKU simultaneously — the best effort-to-impact ratio in the whole project.
- Week 3 — attribute extraction + summaries. Top 50 revenue products: facts into fields, first-two-sentence summaries rewritten, product FAQs added from real support questions.
- Week 4 — collections + feeds. Upgrade the top five collection templates as above; reconcile Merchant Center with on-site data; publish the first two buying guides. Then put the remaining long tail on the automated pipeline rather than a someday list.
Measuring whether it worked
Four signals, checked monthly:
- Assistant spot-checks: the same ten buying questions, same assistants — do you now appear, and which facts do they quote?
- Rich result coverage: Search Console’s product enhancement reports trending toward complete.
- AI referral traffic: sessions from perplexity.ai and chatgpt.com — small absolute numbers today, but the trend line is the point, and those visitors arrive pre-sold.
- Long-tail impressions: attribute-flavoured queries (“bamboo 20-30mmHg wide calf”) appearing in Search Console — evidence the extracted fields are matching real question phrasing.
Expect movement in weeks on the crawler-driven signals and quarters on assistant behaviour — which, as with everything in this space, is the argument for starting before your category’s other stores do.
What complete Product schema actually looks like
For the technically curious — or whoever you forward this to — here is the shape of a complete product record, annotated. (Field names are schema.org vocabulary; your platform or SEO plugin emits the JSON-LD.)
- name, description, image: the description here should be your liftable two-sentence summary, not the full marketing copy — engines display and embed this text.
- brand → Brand: named identically everywhere your products appear. “BuraCare” and “Bura Care” read as two entities.
- sku, gtin13/mpn: the reconciliation keys. With a GTIN, engines connect your listing to the same product’s reviews and prices across the web; without one, you are an island.
- offers → Offer: price, priceCurrency, availability (InStock/OutOfStock/PreOrder), url — per purchasable variant, kept truthful by your platform in real time, plus shippingDetails and hasMerchantReturnPolicy where your plugin supports them: assistants increasingly surface delivery and returns in recommendations.
- aggregateRating + review: wired to your real review system — never hand-typed, which violates guidelines and eventually gets caught.
- additionalProperty → PropertyValue: the extracted attributes — compressionLevel “20-30mmHg”, material “bamboo blend” — the fields that let a machine answer the filtered question.
The test after implementation is not “does it validate” — validators accept technically-correct emptiness. The test is: could a machine reading only the structured data answer every question a buyer would ask before purchasing?
The marketplace angle
If you also sell on Amazon or other marketplaces, your listings there are part of your entity story whether you manage them or not. Assistants cross-reference: same GTIN, different specs between your store and your Amazon listing is a contradiction that costs trust; consistent data plus marketplace review volume is corroborating evidence that strengthens both surfaces. Treat marketplace content as part of the same catalogue project — same attribute source of truth, same summaries adapted per platform’s rules. (Listing creative is its own craft; our Amazon listing image portfolio shows how the visual layer answers buyer questions the same way the data layer does.)
The mistakes we keep un-making for clients
- Schema on the theme’s demo products but not the real catalogue — template edits that never got applied to the live product template.
- Availability frozen at InStock since launch, including for discontinued items — worse than no signal, because it is a detectable lie.
- Reviews rendered only in JavaScript by a third-party widget, invisible to any crawler that doesn’t execute it — the store has 400 reviews and the machines can see zero.
- Duplicate titles across variants (“Compression Socks — Black” × 12) crowding out the attribute-rich titles that match real queries.
- Deleting product pages of sold-out items instead of marking OutOfStock — destroying accumulated authority and every external link pointing at it.
Every one of these is invisible in a browser and glaring in the data layer — which is precisely why they survive for years on otherwise well-run stores.
Related reading: this article is the ecommerce half of a pair — the strategy layer lives in SEO, AEO and GEO: how to get cited by AI search. For the production side, our product content workflow writes catalogue-scale descriptions with the structured attributes extracted as part of the job, and the Shopify CRO checklist turns the traffic these fixes earn into orders.
The bottom line
AI shopping answers are built from the data merchants publish. Complete schema, real attributes, liftable summaries, evidentiary reviews, consistent feeds — none of it is exotic, all of it is work, and the stores that do it first get quoted while competitors wonder why assistants never mention them.
Frequently asked questions
Does this matter if most of my sales come from Google Ads?
Yes — the same structured completeness raises feed quality scores and ad performance today, and AI answers are where a growing share of pre-purchase research happens. The work pays on both surfaces at once.
We have thousands of SKUs — where do we start?
Rank by revenue and start with the top fifty. Fix schema completeness, extract attributes, rewrite the summary sentences. Then automate the long tail — catalogue-scale content is exactly what pipelines are for, as in our Factory Direct Medical case study.
Can AI assistants actually complete purchases?
Assistant-driven checkout is emerging and uneven across platforms — but the recommendation step is already here, and it is where the buying decision happens. Optimising for the recommendation is the durable bet regardless of who ultimately processes the payment.
How do I check how my products appear to AI engines?
Ask them, monthly: pose your category's buying questions to ChatGPT, Perplexity and Google's AI mode. Note whether you appear, what facts they cite, and where those facts came from. Then run a rich-results test on your top pages — the gap between the two views is your to-do list.
Does schema help if my products are handmade or one-of-a-kind?
Even more than usual. Unique items have no GTIN and no cross-web corroboration, so your own structured data is the only machine-readable account of what the piece is, its materials, dimensions and availability. Complete Product markup plus specific, liftable descriptions is how a one-off item becomes findable by the long, precise questions its one right buyer asks.
Do AI engines read PDFs, size charts and spec sheets?
Unreliably at best — and never as trustworthy structured data. Anything decision-critical living inside a PDF or an image (the classic photographed size chart) should also exist as HTML text and attribute fields. Keep the PDF for humans who want it; never let it be the only home of a purchasing fact.
Should I write different descriptions for AI engines than for people?
No — that fork is where content programs go to die. Write one description whose first two sentences answer the buyer question directly and whose remainder persuades a human; the extraction-friendly version and the selling version are the same text in the right order. Machines are reading for the buyer, not instead of them.
How do AI assistants choose which products to recommend?
They retrieve candidates from indexes and feeds, filter them against the question's constraints using structured attributes, price and availability, and justify picks with evidence like reviews. Products whose data cannot answer the question are silently excluded.
What is the highest-impact fix for AI shopping visibility?
Complete Product schema — offers with truthful availability, aggregate ratings, brand and identifiers, and per-variant markup — because template-level fixes lift every product simultaneously.
Where should a large catalogue start?
Rank by revenue and fix the top fifty products first: schema completeness, attributes extracted into fields, and liftable two-sentence summaries. Automate the long tail with a content pipeline.
Written by
BurTech Solution
Engineering team
The BurTech Solution engineering team designs, builds and maintains AI automation, ecommerce stores, SaaS and custom software for growing businesses. Everything on this blog comes from work we ship for clients and run ourselves.
Keep reading
More on seo & ai search.
SEO & AI Search10 min read
FAQ Schema in 2026: Still Worth It?
The rich-result dropdowns are history, but FAQ schema quietly became more valuable, not less: structured Q&A is what answer engines parse when choosing whom to quote. The honest 2026 assessment — what it does now, which pages deserve it, and how to…
Read the article →
SEO & AI Search9 min read
Content Refresh: When to Update, Merge or Delete Old Posts
Your archive is quietly split into winners, fixables and dead weight. The four-way decision framework — update, merge, delete or leave alone — with the criteria, the redirect mechanics, and why AI search makes refresh discipline pay twice.
Read the article →
SEO & AI Search10 min read
Local SEO for Service Businesses: The Google Business Profile Playbook
The map pack runs on relevance, distance and prominence — and the Google Business Profile is the lever. The fields that matter, the review system that compounds, local content, and the honest limits.
Read the article →